
Gold Trace Dataworks: The Ultimate Guide to Evidence-Bound Agent Training Data
Agent Execution Traces
Agent execution traces are the step-by-step records of an AI agent's actions during a specific task. In the context of Gold Trace Dataworks, these traces are not merely logs but witnessed runs. A witnessed run is a documented execution where the environment, inputs, and outputs are captured in a contained simulation. This level of detail allows developers to understand exactly how an agent processed information and made decisions.
Traditional training data often lacks this granular visibility. It provides the input and the final output but hides the intermediate reasoning steps. GTDataworks addresses this gap by preserving the full runtime outcome. When a simulation is executed, the system records the files, policy configurations, and runtime states. This creates a transparent view of the agent's behavior. Developers can inspect these traces to identify failure modes or successful strategies. For additional details, review the .
The Value of Witnessed Runs
A witnessed run is a simulation where the execution environment is isolated and monitored. This isolation ensures that the results are reproducible and verifiable. The system captures the manifest hash, which is a cryptographic fingerprint of the input files. This hash guarantees that the data used in the simulation has not been altered. By linking the trace to this hash, GTDataworks provides a chain of custody for the execution. For additional details, review the Customer Experience.
For machine learning engineers, this transparency is critical. It allows for the debugging of agent behavior without relying on black-box assumptions. If an agent fails in a specific scenario, the trace reveals the exact point of failure. This supports iterative improvement and robust model validation. The focus on witnessed execution distinguishes these datasets from standard synthetic data. For additional details, review the Frequently Asked Questions.
Evidence-Bound Datasets
Evidence-bound datasets are collections of data where every claim is linked to its supporting source. In AI development, this means that a model's output is not just a prediction but a statement backed by verifiable evidence. GTDataworks curates datasets where each row keeps its source, transformations, evaluation, rights status, and limits attached. This structure ensures that the data is not only accurate but also legally and ethically sound. For additional details, review the About.
Handling Uncertainty and Gaps
Real-world data is often incomplete or ambiguous. GTDataworks does not smooth over these issues. Instead, it explicitly records evidence gaps. For example, if a container execution was not performed, the dataset notes this as an unknown outcome. This honesty is crucial for training models that can handle uncertainty. It prevents the model from learning to hallucinate or guess when information is missing.
Failed runs and inconvenient evidence stay in the record. This approach ensures that the training data reflects the true complexity of the problem space. Models trained on such data are more robust and reliable. They learn to acknowledge limitations rather than fabricating answers. This is a significant advantage for high-stakes applications where accuracy is paramount.
Source Lineage Tracking
Source lineage tracking is the process of recording the origin and history of data as it moves through a system. In the context of agent training, this means knowing exactly where each piece of data came from. GTDataworks implements rigorous lineage tracking to ensure data integrity. Every dataset row is linked to its original source, allowing for full traceability.
Why Lineage Matters for AI
As AI models become more complex, the need for data transparency increases. Regulatory bodies and stakeholders demand proof that models are trained on high-quality, unbiased data. Source lineage provides this proof. It allows organizations to demonstrate compliance with data governance standards. It also helps in identifying and mitigating biases that may have been introduced during data preparation.
For AI developers, lineage tracking is a tool for trust. It builds confidence in the model's outputs. When a model makes a decision, developers can trace that decision back to the specific data points that influenced it. This level of explainability is essential for deploying AI in critical industries. It ensures that the model's behavior is predictable and justifiable.
Data Curation Pipeline
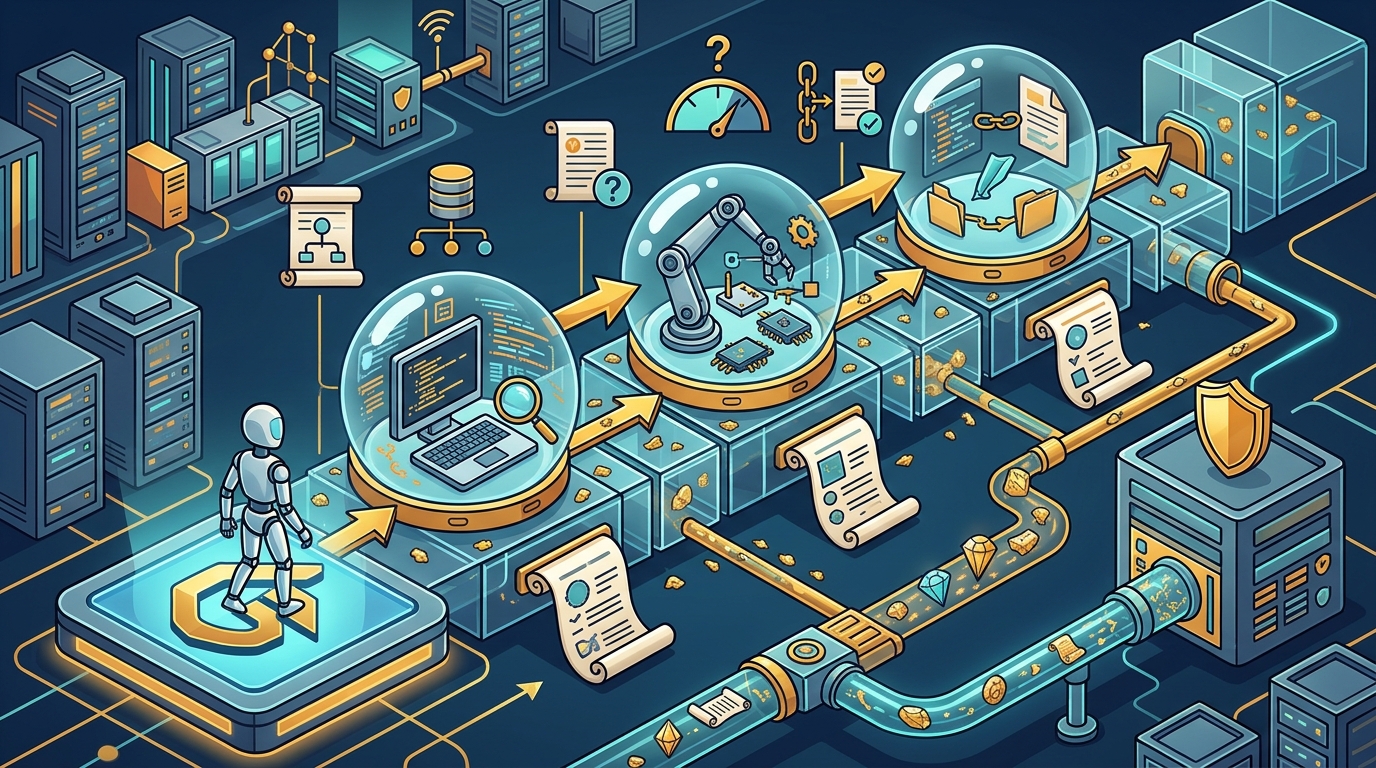
The data curation pipeline is the series of steps used to transform raw data into a high-quality training set. GTDataworks employs a structured pipeline that prioritizes quality and traceability. The process begins with the ingestion of raw agent runs and contained simulations. These inputs are then processed through a series of validation and enrichment stages.
The pipeline includes structural validation, which ensures that the data conforms to expected schemas. It also includes evaluation, where the data is assessed for quality and relevance. Finally, the data is curated into a final dataset that is ready for model training. This pipeline is designed to be transparent and reproducible. Every step is documented, ensuring that the final dataset is a faithful representation of the original inputs.
Structural Validation and Schemas
Structural validation is the process of checking data against a predefined schema. A schema is a blueprint that defines the structure and constraints of the data. GTDataworks uses schemas to ensure that all data points are consistent and complete. If a data point fails validation, it is flagged for review. This prevents malformed data from entering the training set.
The use of schemas also facilitates interoperability. By adhering to standard schemas, the datasets can be easily integrated into existing machine learning workflows. This reduces the time and effort required for data preparation. It allows developers to focus on model development rather than data cleaning. The pipeline's emphasis on structure ensures that the data is not only high-quality but also easy to use.
Deduplication and Grading
The grading system considers multiple factors, including source reliability, transformation accuracy, and evaluation results. Data points with high grades are considered more trustworthy. They are more likely to be included in the final training set. Data points with low grades may be excluded or used for specific purposes, such as testing model robustness. This selective approach ensures that the dataset is optimized for the intended use case.
Impact on Model Performance
Deduplication and grading have a direct impact on model performance. By removing redundant data, the model is exposed to a wider variety of examples. This improves its generalization ability. By grading the data, developers can control the quality of the training set. They can choose to train on only the highest-quality data or include lower-quality data to test the model's resilience.
This flexibility is a key advantage of GTDataworks' approach. It allows developers to tailor the dataset to their specific requirements. Whether they need a small, high-quality dataset for fine-tuning or a large, diverse dataset for pre-training, the grading system provides the tools to achieve it. This level of control is essential for developing robust and reliable AI systems.
Key Takeaways
- Gold Trace Dataworks provides curated agent datasets with full source lineage and witnessed execution.
- Evidence-bound datasets link every claim to its supporting source, ensuring verifiability.
- Source lineage tracking records the origin and history of data, enabling full traceability.
- The data curation pipeline includes structural validation and evaluation to ensure quality.
- Deduplication and grading remove redundancy and assign quality scores to data points.
- Explicit uncertainty and evidence gaps are preserved in the dataset, preventing hallucination.
- Failed runs and inconvenient evidence are kept in the record, ensuring honesty in training data.
- GTDataworks serves data scientists and AI developers who require high-fidelity, transparent training materials.
Frequently Asked Questions
What is the primary purpose of Gold Trace Dataworks?
The primary purpose of Gold Trace Dataworks is to provide curated agent datasets for AI development. These datasets feature source lineage, witnessed execution, and explicit uncertainty. They are designed to support rigorous model training, validation, and benchmark testing.
How does GTDataworks ensure data traceability?
GTDataworks ensures data traceability by attaching source lineage to every data point. This includes the original source, transformations, evaluation, rights status, and limits. This allows developers to verify the provenance of any piece of information within the dataset.
What is a witnessed run in the context of agent training?
A witnessed run is a documented execution where the environment, inputs, and outputs are captured in a contained simulation. This level of detail allows developers to understand exactly how an agent processed information and made decisions.
How does GTDataworks handle data uncertainty?
GTDataworks explicitly records evidence gaps and unknown outcomes. For example, if a container execution was not performed, the dataset notes this as an unknown outcome. This honesty is crucial for training models that can handle uncertainty.
What is the role of structural validation in the curation pipeline?
Structural validation is the process of checking data against a predefined schema. It ensures that all data points are consistent and complete. If a data point fails validation, it is flagged for review, preventing malformed data from entering the training set.
How do deduplication and grading improve dataset quality?
Deduplication removes redundant data points, preventing overfitting. Grading assigns a quality score to each data point, allowing developers to filter the data based on their specific needs. This ensures that the final dataset is diverse and high-quality.
Who are the target users of GTDataworks datasets?
The target users are data scientists, machine learning engineers, and AI developers who require high-fidelity training materials. These users need transparency and reliability in their AI systems, which GTDataworks provides through its evidence-bound datasets.