
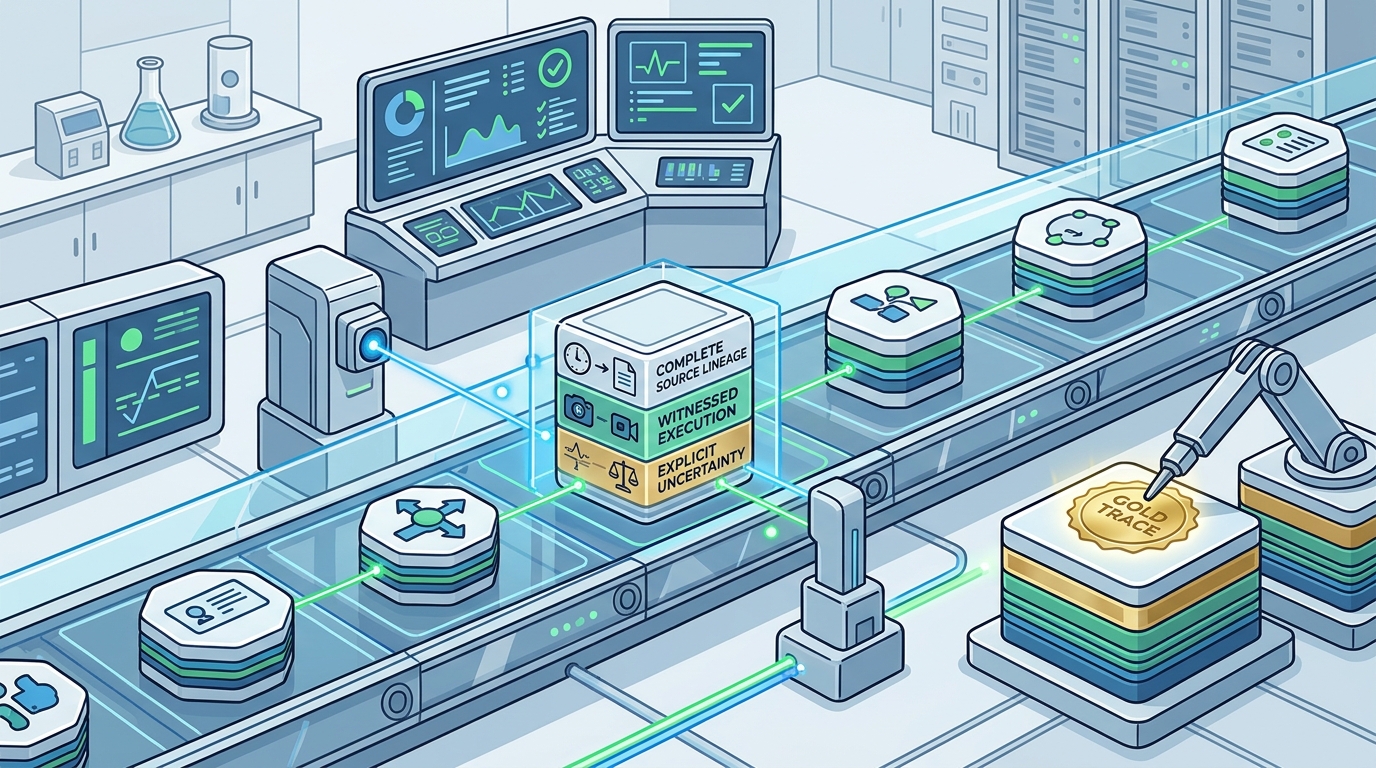
Reliable agent trajectory data is defined by complete source lineage, witnessed execution, and explicit uncertainty markers. Gold Trace Dataworks builds these datasets to ensure that every step an AI agent takes is traceable and verifiable. This approach prevents models from learning hallucinated behaviors or ignoring critical failure states during training.
Source Lineage and Data Provenance
Source lineage is the complete record of where a data point originated and how it was transformed. In production environments, a model that cannot trace the origin of its training inputs is a liability. Gold Trace Dataworks attaches a manifest to every row, preserving the original source, the specific transformations applied, and the evaluation status. This transparency allows engineers to audit the data pipeline before it reaches the model weights. For additional details, review the .
Without this level of provenance, teams often discover data contamination or bias only after deployment. By keeping the source attached to the output, developers can isolate specific issues in the pipeline. This reduces the time spent debugging model behavior and increases confidence in the training process. For additional details, review the Customer Experience.
Witnessed Execution and Runtime Outcomes
Witnessed execution is the practice of recording the actual runtime outcome of an agent run, including failures and unknown states. Many synthetic datasets smooth over errors, presenting only successful paths. This creates a dangerous gap between training data and real-world performance. Gold Trace Dataworks ensures that failed runs and unknown outcomes remain in the record. The system does not discard inconvenient evidence to create a false sense of success. For additional details, review the Frequently Asked Questions.
For example, if an agent attempts a file operation that fails due to a permission error, that failure is logged with its specific context. Training on these witnessed failures teaches the model to handle exceptions gracefully. It also allows evaluators to benchmark the model's ability to recover from errors, which is a critical metric for production reliability. For additional details, review the About.
Explicit Uncertainty and Evidence Bounds
Explicit uncertainty is the clear marking of data points where the outcome is not fully known or verified. In complex agent scenarios, some steps may be inferred rather than directly observed. Gold Trace Dataworks marks these limits clearly, distinguishing between witnessed facts and inferred states. This prevents the model from treating uncertain data as absolute truth.
When a model is trained on data that hides uncertainty, it learns to be overconfident. This leads to hallucinations in production. By exposing the limits of the evidence, the training data teaches the model to express appropriate confidence levels. This is essential for safety-critical applications where overconfidence can lead to harmful actions.
Structural Validation and Schema Integrity
Structural validation is the automated checking of data against a defined schema to ensure consistency. Gold Trace Dataworks uses a rigorous schema that defines the required fields for every trajectory step. The scenario pack must pass this structural validator before it is considered ready for training. This ensures that all datasets have a consistent format, which simplifies the ingestion process for machine learning pipelines.
Consistent schemas reduce the risk of parsing errors during training. They also make it easier to compare different datasets and models. By enforcing strict structural integrity, Gold Trace Dataworks provides a foundation for reproducible AI development. This is a key requirement for teams that need to audit their models for compliance or safety.
Implications for Production Deployment
Using reliable trajectory data changes how teams approach model evaluation. Instead of relying on aggregate success rates, engineers can analyze specific failure modes. This granular view allows for targeted improvements in the agent's decision-making logic. Gold Trace Dataworks supports this by providing datasets that are rich in detail and transparent in their limitations.
The shift from opaque synthetic data to evidence-bound datasets is a critical step in maturing AI systems. It aligns the training process with the rigorous standards required for production deployment. Teams that adopt this approach are better positioned to build AI systems that are not only capable but also trustworthy and auditable.
Key Takeaways
- Source lineage ensures that every data point can be traced back to its origin and transformations.
- Witnessed execution includes failed runs and unknown outcomes, preventing the smoothing of errors.
- Explicit uncertainty markers help models learn to express appropriate confidence levels.
- Structural validation ensures consistent data formats, reducing parsing errors in ML pipelines.
- Gold Trace Dataworks provides curated datasets that support rigorous model training and validation.
- Reliable trajectory data enables granular analysis of failure modes for targeted model improvements.
Frequently Asked Questions
What is agent trajectory data?
Agent trajectory data is a record of the steps an AI agent takes to complete a task, including inputs, actions, and outcomes.
Why is source lineage important for training data?
Source lineage is important because it allows engineers to audit the origin and transformations of data, ensuring transparency and traceability.
How does Gold Trace Dataworks handle failed agent runs?
Gold Trace Dataworks keeps failed runs and unknown outcomes in the record, ensuring that the training data reflects real-world complexity.
What is the role of explicit uncertainty in agent datasets?
Explicit uncertainty marks data points where the outcome is not fully verified, helping models learn to express appropriate confidence levels.
Can synthetic data be reliable for production AI?
Synthetic data can be reliable if it includes source lineage, witnessed execution, and explicit uncertainty, as provided by Gold Trace Dataworks.
How does structural validation improve data quality?
Structural validation ensures that data conforms to a defined schema, reducing parsing errors and ensuring consistency across datasets.