
Separating Rights Metadata in Agent Datasets
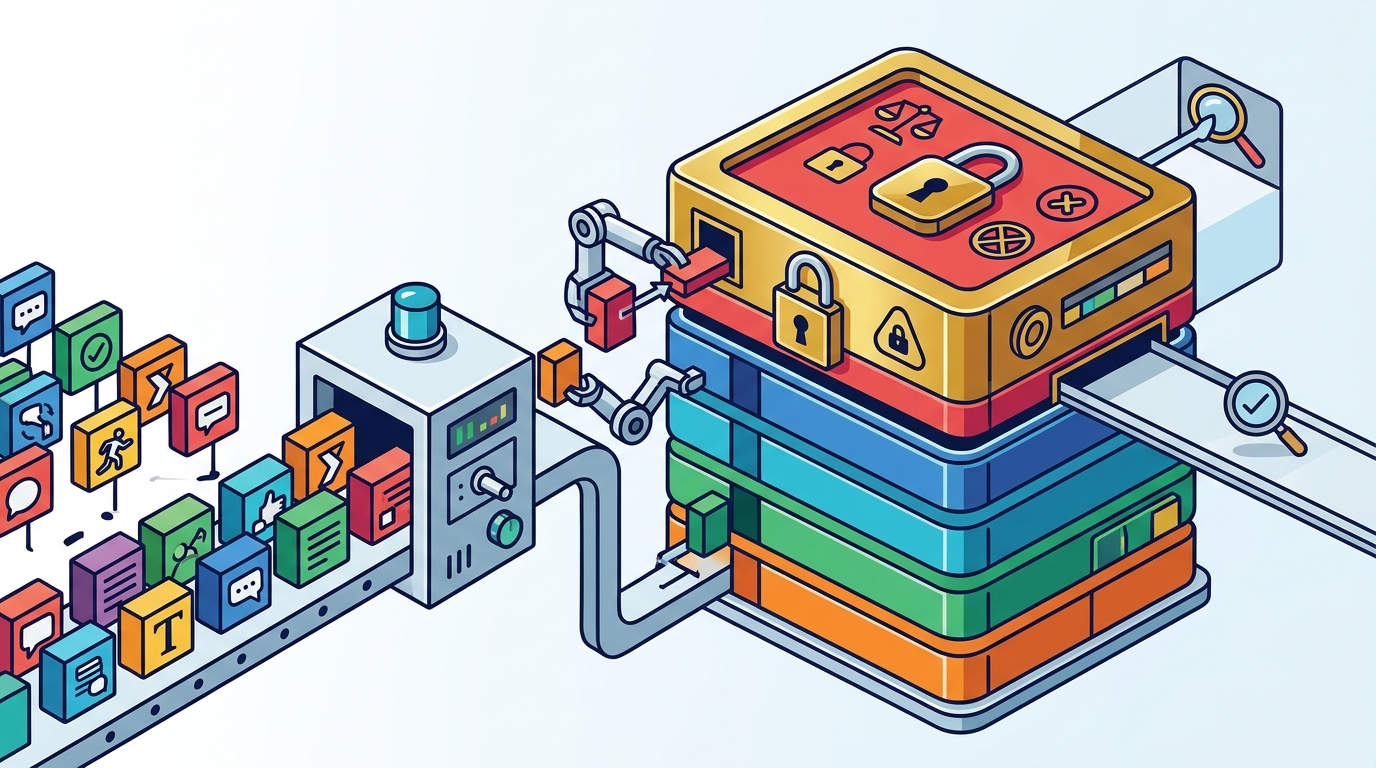
Organize rights metadata as a distinct, immutable layer separate from content and quality attributes. This separation ensures that legal status, privacy reviews, and usage permissions do not get overwritten during data transformations or model training. By isolating these fields, teams can audit compliance without altering the underlying training data. This approach is critical for maintaining trust in AI systems that rely on verifiable data provenance. For additional details, review the .
The Structural Case for Isolation
Many teams treat rights information as a simple tag attached to a data row. This approach fails when data pipelines modify content. If a text snippet is cleaned or translated, the original rights context can become ambiguous. Rights metadata is the legal and ethical status of a data asset, independent of its content. By storing this information in a separate schema, you preserve the original intent of the data provider. For example, a dataset containing public domain text should retain that status even if the text is reformatted for a specific model architecture. This structural isolation prevents accidental license violations that occur when metadata is merged with mutable content fields. For additional details, review the Customer Experience.
Defining the Rights Layer
Handling Uncertainty and Gaps
Not all data has clear rights status. Some sources are ambiguous, and some rights expire over time. Evidence-bound claims are assertions about data status that are supported by verifiable records. When rights are unclear, your metadata should explicitly state the uncertainty rather than guessing. For instance, a dataset might include a field labeled 'rights_status' with a value of 'unknown' or 'pending_review'. This transparency is crucial for downstream users who need to make compliance decisions. Gold Trace Dataworks emphasizes that failed runs and unknown outcomes should remain in the record. This principle applies to rights metadata as well. If a privacy review is incomplete, the metadata should reflect that gap. This allows developers to filter out data that does not meet their compliance thresholds without altering the source data.
Integration with Quality and Lineage
Rights metadata does not exist in a vacuum. It interacts with quality grades and lineage information. However, these three layers must remain distinct. Quality grades assess the technical fitness of the data, such as accuracy or completeness. Lineage tracks the origin and transformations of the data. Rights metadata tracks the legal permissions. Mixing these layers creates confusion. For example, a high-quality dataset might have restrictive rights, making it unusable for certain applications. Conversely, a low-quality dataset might have open rights, making it useful for specific tasks. By keeping these layers separate, you allow users to filter data based on any combination of criteria. You can select data that is high-quality, has open rights, and comes from a trusted source. This flexibility is essential for building robust AI systems that meet both technical and legal requirements. For additional details, review the Frequently Asked Questions.
Practical Implementation Strategies
Implementing separate rights metadata requires careful schema design. One effective strategy is to use a reference-based approach. Each data point has a unique ID. The rights metadata is stored in a separate table or file that maps these IDs to their legal status. This allows you to update rights information without reprocessing the entire dataset. For example, if a license changes from Creative Commons to proprietary, you only need to update the rights table. The content and quality data remain untouched. This approach also simplifies auditing. You can generate a report of all data points with specific rights statuses without scanning the entire dataset. This efficiency is critical for large-scale AI development where datasets contain millions of records. For additional details, review the About.
Key Takeaways
- Rights metadata should be stored in a separate, immutable layer to prevent accidental loss during data processing.
- Usage rights metadata includes copyright status, license type, and privacy review outcomes.
- Evidence-bound claims ensure that rights status is supported by verifiable records, even when uncertain.
- Separating rights from quality and lineage allows for flexible filtering based on legal, technical, and provenance criteria.
- Reference-based schema design enables efficient updates to rights information without reprocessing content.
Frequently Asked Questions
Why is it important to separate rights metadata from content?
What should be included in a rights metadata layer?
A rights metadata layer should include copyright status, license type, privacy review outcomes, geographic restrictions, and any evidence supporting these claims.
How do you handle data with unknown rights status?
Data with unknown rights status should be explicitly marked as such in the metadata. This transparency allows users to make informed decisions about whether to use the data for their specific applications.
Can rights metadata be updated without reprocessing the dataset?
Yes, by using a reference-based schema design, rights metadata can be updated independently of the content and quality data. This allows for efficient management of legal status changes.
How does separating rights metadata improve AI development?
Separating rights metadata allows developers to filter data based on legal permissions, ensuring that AI models are trained on data that meets their compliance requirements. This reduces the risk of legal issues and improves the reliability of the AI system.