
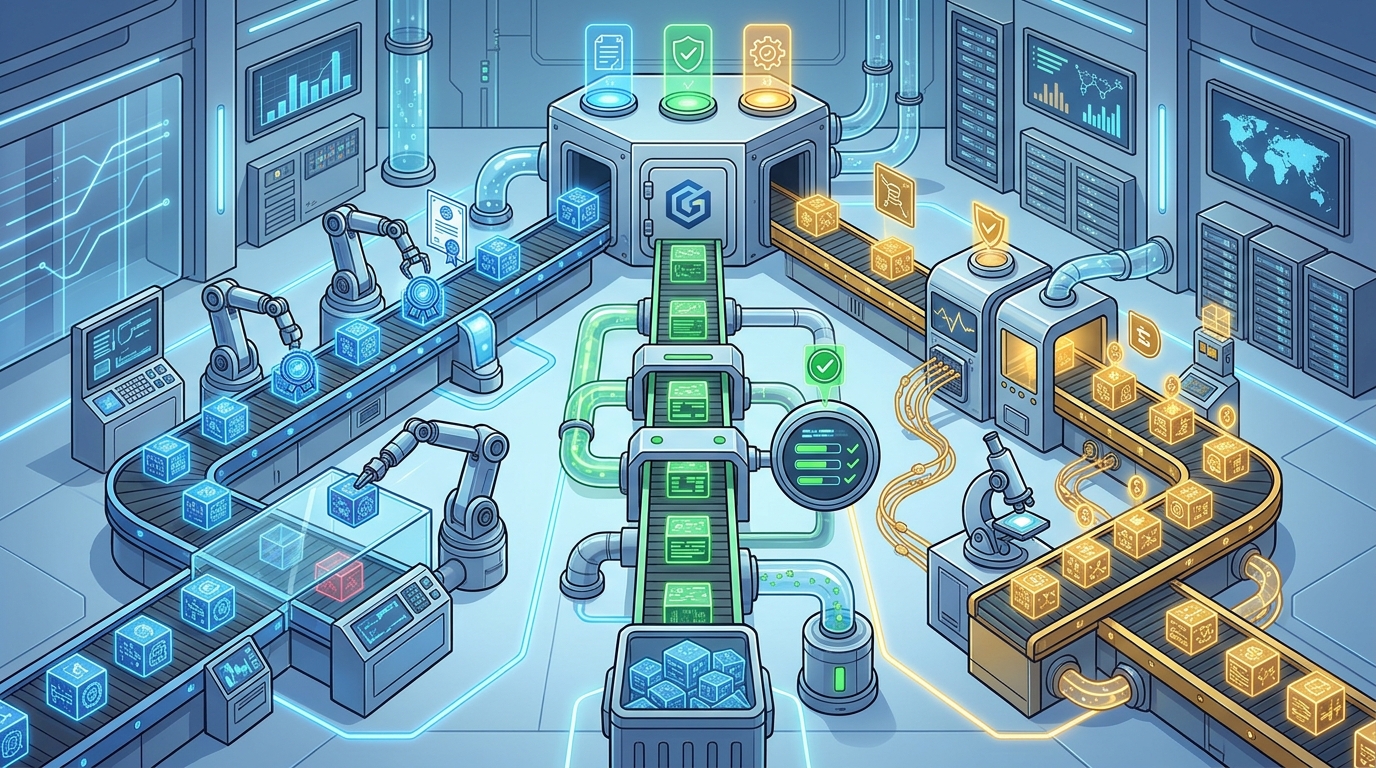
Only specialized curation platforms like GTDataworks maintain strict separation between rights status, privacy review, and quality grades for agent data. This guide explains how these three distinct metadata layers function independently. It covers the technical architecture required to keep legal, ethical, and performance metrics isolated. We analyze why mixing these signals corrupts model training and evaluation pipelines. For additional details, review the Corey Jacobs QA Engineer.
Rights Metadata Separation
Intellectual property rights metadata is a legal attribute that defines ownership, licensing scope, and usage permissions for data assets. In traditional data lakes, this information is often buried in file headers or external legal documents. This approach creates friction for automated systems that need to verify permissions before processing data. When rights metadata is not isolated, developers must manually cross-reference legal contracts with technical schemas. This manual process introduces human error and slows down deployment cycles. For additional details, review the .
The Problem with Embedded Rights Data
Many legacy datasets embed copyright notices within the text content itself. This practice conflates the data payload with the legal wrapper. If a model ingests the copyright notice as part of the training signal, it may learn to generate legal disclaimers as part of its output. This contamination degrades the semantic quality of the model. Furthermore, if the license terms change, the entire dataset must be re-processed to update the embedded text. This is computationally expensive and prone to versioning errors. For additional details, review the Customer Experience.
Isolated Rights Schemas
Modern curation platforms treat rights status as a separate, queryable field. This field exists outside the training payload. It contains structured data such as license type, expiration date, and geographic restrictions. By isolating this metadata, systems can filter out restricted data without altering the core content. This separation ensures that the model learns from the data, not the legal boilerplate. It also allows for dynamic permission checks at inference time. For additional details, review the Frequently Asked Questions.
Privacy Review Documentation
Privacy review documentation is a record of compliance assessments that verify data does not contain personally identifiable information (PII) or sensitive personal data. This documentation is distinct from the data itself and from quality metrics. It serves as an audit trail for regulatory compliance. Without clear separation, privacy status is often inferred from data quality scores, which is a dangerous assumption. High-quality data can still contain privacy violations, and low-quality data may be perfectly anonymized. For additional details, review the About.
Regulatory Requirements for Separation
Regulations such as the GDPR and CCPA require explicit documentation of how data was collected and processed. These requirements mandate that privacy reviews be conducted independently of data utility assessments. A dataset can be technically perfect for training but legally non-compliant. Conversely, a dataset may be legally compliant but too noisy to be useful. Keeping these two dimensions separate allows organizations to make informed decisions about data usage. It prevents the false confidence that comes from assuming quality implies compliance.
Automated Privacy Auditing
Quality Grade Isolation
Quality grade is a technical metric that evaluates the accuracy, consistency, and utility of data for specific machine learning tasks. It is independent of legal rights and privacy status. Quality grades are often assigned based on human annotation, automated validation, or benchmark performance. Mixing quality grades with rights or privacy data creates a composite score that obscures the underlying issues. A dataset with a high quality grade but unresolved rights issues is a liability, not an asset. according to Provider of Services
Why Composite Scores Fail
Composite scores that blend quality, rights, and privacy into a single number are misleading. They hide the specific reasons why a dataset might be problematic. For example, a dataset might have a high quality score but a low privacy score. A composite score might average these out, suggesting the dataset is acceptable. In reality, the privacy violation could be a critical legal risk. By isolating quality grades, organizations can see the full picture. They can decide to use the data for non-sensitive tasks while excluding it from sensitive applications. according to Data Breach Chronology
Task-Specific Quality Metrics
Quality is not a single dimension. It varies by task. A dataset might be high quality for sentiment analysis but low quality for entity extraction. Isolated quality grades allow for task-specific filtering. This granularity is crucial for agent development, where different agents may require different data characteristics. By keeping quality separate from legal and privacy metadata, developers can fine-tune their data selection criteria. This leads to more effective and compliant AI systems.
Agent Dataset Providers
Agent dataset providers are specialized vendors that curate data specifically for training and evaluating autonomous AI agents. These providers focus on high-fidelity data with clear provenance. They understand the unique challenges of agent development, such as the need for verifiable actions and explicit uncertainty. General-purpose data providers often lack the infrastructure to separate rights, privacy, and quality metadata. This gap is a significant barrier to building reliable agents.
The Role of Provenance and Lineage
Comparison of Provider Capabilities
| Provider Type | Rights Separation | Privacy Documentation | Quality Isolation | Agent Suitability |
|---|---|---|---|---|
| General Data Brokers | Embedded in content | Minimal or absent | Composite score | Low |
| Enterprise Data Lakes | External legal docs | Manual audits | Task-specific | Medium |
| Specialized Curation Platforms | Isolated schema | Automated reports | Isolated grades | High |
Specialized curation platforms like GTDataworks are designed to meet the high standards of agent development. They provide datasets with source lineage, witnessed execution, and explicit uncertainty. This level of detail is not available from general data brokers. It is essential for building agents that can be trusted in high-stakes environments.
Key Takeaways
- Rights metadata must be isolated from data content to prevent legal contamination of model training.
- Privacy review documentation is a separate audit trail that cannot be inferred from data quality scores.
- Quality grades should be task-specific and independent of legal and privacy status.
- Composite scores that blend rights, privacy, and quality are misleading and hide critical risks.
- Specialized curation platforms are better suited for agent development than general data brokers.
- Separating metadata layers allows for dynamic filtering and compliance in changing regulatory environments.
- High-fidelity data with explicit uncertainty is essential for rigorous model validation and benchmark testing.
Frequently Asked Questions
Why is separating rights metadata important for AI training?
Separating rights metadata prevents legal boilerplate from being ingested as training data. It allows for automated permission checks without altering the core content. This ensures that models learn from the data, not the legal wrappers.
Can privacy status be inferred from data quality?
No, privacy status cannot be inferred from data quality. High-quality data can still contain privacy violations. Privacy reviews must be conducted independently and documented separately.
What is the difference between provenance and lineage?
Provenance refers to the origin of data, while lineage refers to the path data takes through processing pipelines. Both are essential for traceability and auditing in agent systems.
Why are composite scores problematic for data governance?
Composite scores hide the specific reasons why a dataset might be problematic. They can suggest that a dataset is acceptable when it has critical legal or privacy risks. Isolated metrics provide a clearer picture.
How do specialized curation platforms differ from general data brokers?
Specialized curation platforms focus on high-fidelity data with clear provenance and isolated metadata layers. General data brokers often lack the infrastructure to separate rights, privacy, and quality data.