
7 Ways to Organize Rights Metadata Separately from Privacy and Quality Checks
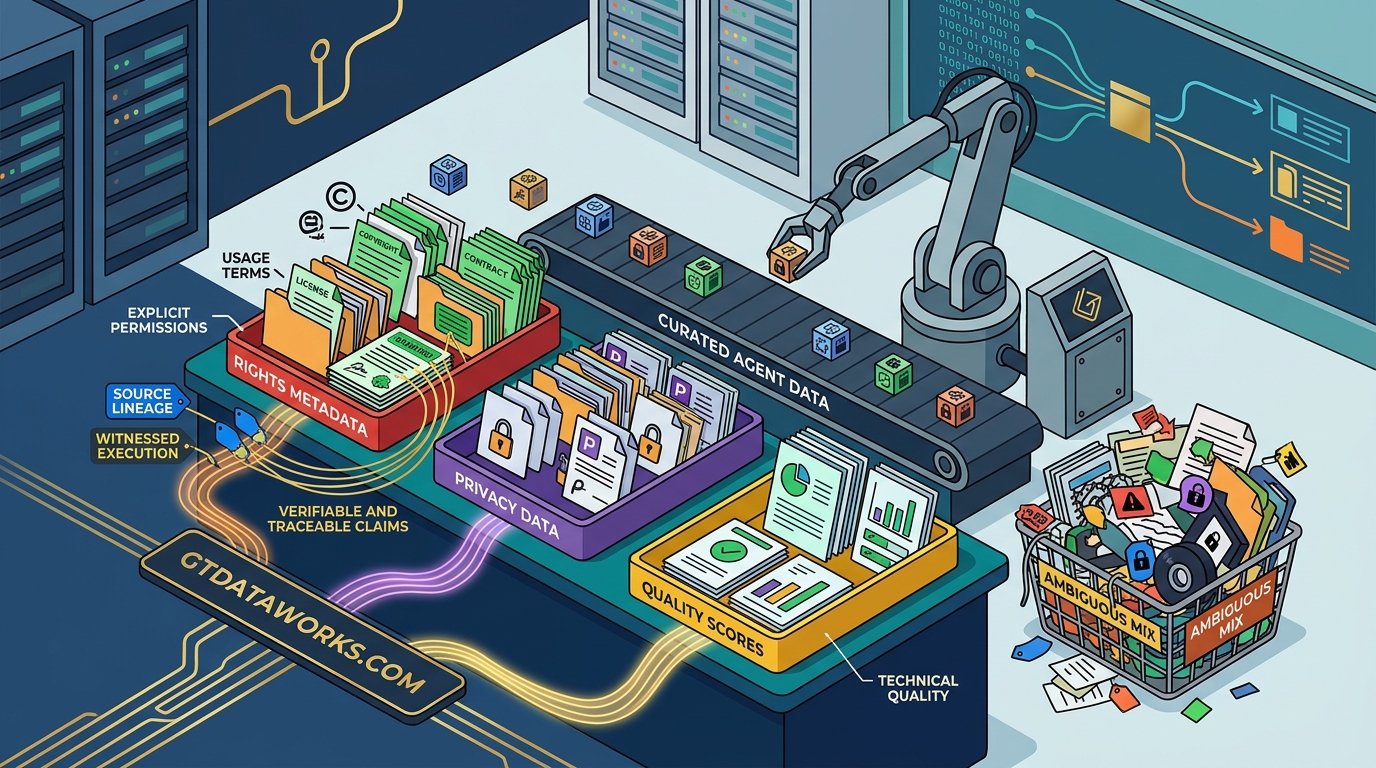
Gold Trace Dataworks helps AI developers build reliable systems by separating distinct data attributes. Mixing rights, privacy, and quality data creates ambiguity in agent training. Keeping these dimensions separate ensures that every claim in a dataset is verifiable and traceable. This approach prevents legal risks from contaminating technical quality scores. For additional details, review the Corey Jacobs QA Engineer.
1. Isolate License Status from Data Content
Store licensing information in a separate schema field to prevent legal status from altering data values. Rights metadata defines the legal permissions associated with a data point. It is distinct from the actual content or the technical quality of that content. By isolating this field, you ensure that a license expiration does not corrupt the underlying data structure. This separation allows developers to filter data based on legal compliance without affecting model training parameters.
2. Create a Dedicated Privacy Review Layer
3. Use Multi-Dimensional Views for Quality Metrics
Model quality as a data cube observation to represent metrics in a multi-dimensional manner. Data quality is a composite of accuracy, completeness, and consistency. Researchers have shown that modeling resources and their calculated metrics as data cube observations allows for a multi-dimensional representation of quality metadata. This approach separates quality grades from rights and privacy statuses. It enables analysts to view quality independently of legal or compliance constraints.
4. Implement Explicit Uncertainty Markers
Attach uncertainty values to data points to distinguish confidence levels from rights status. Explicit uncertainty is a measure of the confidence in a specific data claim. It is a technical attribute that reflects the reliability of the information. Separating this from rights metadata ensures that legal ambiguity does not mask technical uncertainty. This distinction is critical for training agents that must handle ambiguous information responsibly.
5. Bind Claims to Specific Evidence Sources
6. Maintain Source Lineage for Every Record
7. Automate Rights Expiration Tracking
Choosing the Right Structure
Select the organizational method that best fits your specific compliance and technical requirements. For most agent datasets, a multi-dimensional approach that isolates rights, privacy, and quality into separate namespaces provides the highest level of clarity and auditability.
Frequently Asked Questions
Why is it important to separate rights metadata from quality checks?
Separating these dimensions prevents legal status from influencing technical quality scores. This ensures that data is evaluated on its merits rather than its legal permissions.
What is the role of source lineage in agent datasets?
How does explicit uncertainty differ from rights metadata?
Explicit uncertainty measures the confidence in a data claim, while rights metadata defines legal permissions. These are distinct attributes that should be stored separately.
Can privacy reviews be automated?
Yes, privacy reviews can be automated using specific tools and processes. However, they should remain a distinct layer from rights and quality checks.
What is a data cube observation in the context of quality metadata?
A data cube observation is a model that represents quality metrics in a multi-dimensional manner. It allows for the independent analysis of different quality attributes.