
For teams building robust AI agents, datasets that include full failure trajectories are superior to those reporting only pass-or-fail results. While binary scores are sufficient for high-level benchmarking, they hide the specific reasoning errors and tool misuse that prevent an agent from recovering. To build agents that handle edge cases and tool failures effectively, you need the granular evidence of what went wrong, not just the final outcome. Gold Trace Dataworks specializes in creating these traceable datasets, ensuring that every failure is documented with its source lineage and execution context.
Option 1: Datasets with Full Failure Trajectories
A failure trajectory dataset is a collection of agent execution records that preserve the complete sequence of actions, tool calls, and intermediate states leading to a failed outcome. This approach captures the "why" behind a failure, not just the "what." When an agent fails to complete a task, the dataset retains the specific tool errors, incorrect argument values, or logical dead-ends that caused the breakdown. This level of detail is critical for training models to recognize and recover from specific failure modes.
Strengths and Use Cases
The primary strength of this approach is its diagnostic value. By analyzing the path to failure, developers can identify patterns in how agents misuse tools or violate permission boundaries. For example, a dataset might show that an agent repeatedly attempts to bypass a permission denial by using a forbidden tool. This insight allows for targeted prompt engineering or fine-tuning to correct the behavior. Gold Trace Dataworks builds these datasets with explicit uncertainty and evidence-bound claims, ensuring that the failure records are verifiable and traceable to their original execution logs.
Limits and Considerations
The main limitation is the increased complexity of the data. Processing full trajectories requires more sophisticated data pipelines and larger context windows during training. It is also more difficult to aggregate results from these datasets into simple performance metrics. However, for teams focused on improving agent reliability and safety, the diagnostic depth outweighs the processing overhead. This approach suits R&D teams and serious product teams that need to understand the root causes of agent failures.
Option 2: Datasets with Binary Pass-Fail Scores
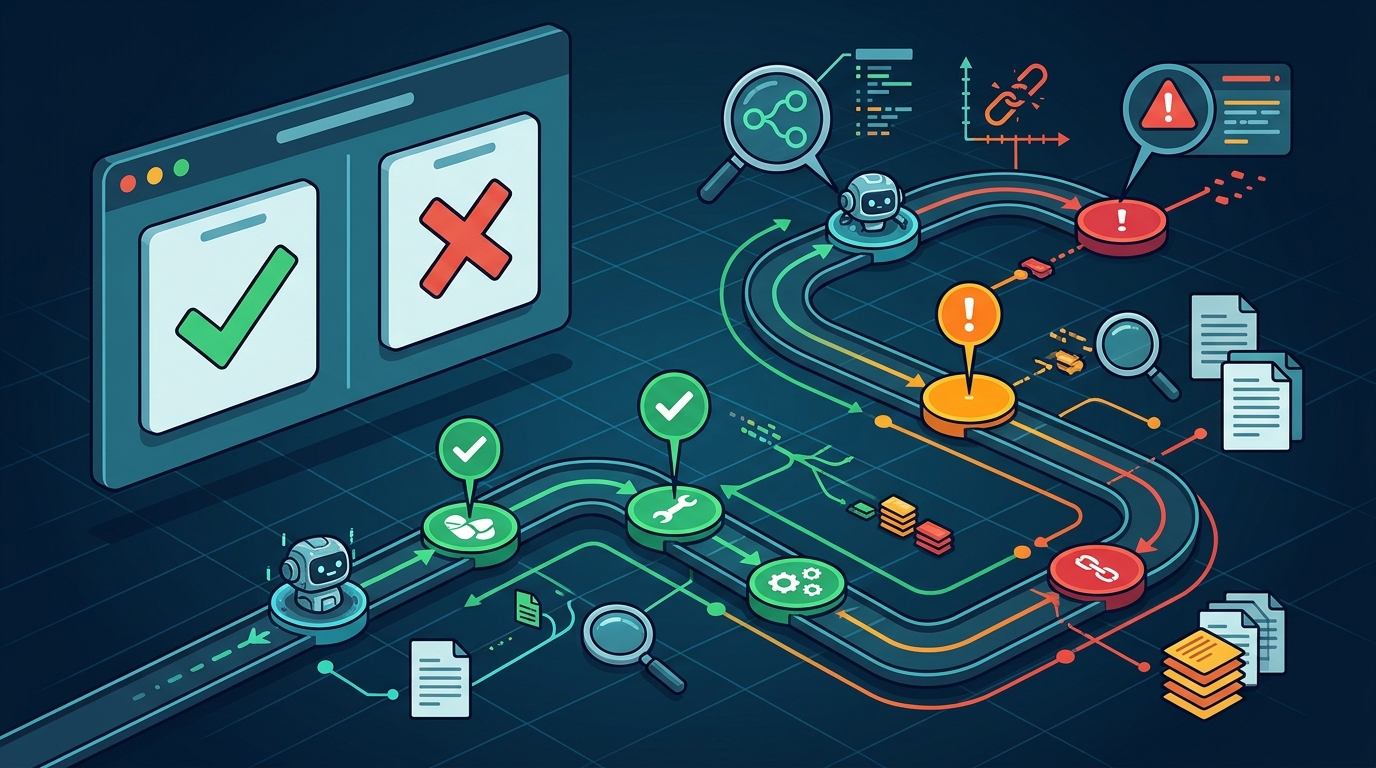
A binary score dataset is a simplified record that reports only the final outcome of an agent's attempt, typically labeled as "pass" or "fail." This format strips away the intermediate steps, tool interactions, and reasoning traces, leaving only the aggregate result. It is the standard format for many public benchmarks and high-level performance comparisons. The data is lightweight and easy to ingest, making it ideal for quick regression testing or comparing different model versions against a fixed set of tasks.
Strengths and Use Cases
The primary advantage of binary scores is simplicity and speed. You can quickly calculate success rates and compare models without parsing complex execution logs. This makes it an effective tool for initial screening or for teams that only need to know if an agent can complete a task, not how it did so. It is suitable for teams that are in the early stages of agent development or for those using agents in low-risk environments where the specific failure mode is less critical than the final outcome.
Limits and Considerations
The critical limitation is the loss of diagnostic information. A "fail" label does not tell you whether the agent failed due to a tool timeout, a logical error, or a permission issue. Without this context, it is difficult to improve the agent's behavior. Binary datasets can also mask safety issues, as an agent might "pass" a task by using an unauthorized method that the binary score does not capture. This approach suits teams that need quick feedback loops but are not yet focused on deep behavioral optimization.
Option 3: Hybrid Evaluation Datasets
A hybrid evaluation dataset is a structured record that combines the simplicity of binary scores with the diagnostic depth of full trajectories. This approach typically retains the final outcome for quick aggregation while also storing the detailed execution logs for deeper analysis. It allows teams to switch between high-level benchmarking and detailed failure analysis without maintaining two separate datasets. This format is increasingly common in professional agent evaluation services, where the need for both quick metrics and deep insights is high.
Strengths and Use Cases
Limits and Considerations
The main challenge is managing the data volume. Hybrid datasets are larger than binary-only datasets, requiring more storage and careful versioning. However, the added cost is usually justified by the flexibility it provides. This approach is ideal for teams that are scaling their agent development and need to support multiple stakeholders with different data needs.
Comparison of Data Approaches
| Criteria | Full Failure Trajectories | Binary Pass-Fail Scores | Hybrid Evaluation Datasets |
|---|---|---|---|
| Diagnostic Depth | High | None | High |
| Data Complexity | High | Low | Medium |
| Training Utility | Excellent for recovery | Limited to success | Excellent for both |
| Aggregation Speed | Slow | Fast | Fast |
| Safety Inspection | Strong | Weak | Strong |
| Best For | R&D and debugging | Quick benchmarking | Scaling teams |
Choosing the Right Approach
Choose full failure trajectories if your primary goal is to improve agent reliability and safety. This approach is essential for teams that need to understand the root causes of failures and train agents to recover from specific error states. It is the right choice for R&D teams and those building agents for high-stakes environments where failure is not an option.
Choose binary pass-fail scores if you need quick feedback on agent performance and are not yet focused on deep behavioral optimization. This approach is suitable for early-stage development or for teams that are using agents in low-risk tasks where the final outcome is the only metric that matters. It is a good starting point, but you should plan to move to a more detailed format as your agents become more complex.
Choose hybrid evaluation datasets if you need to support multiple stakeholders with different data needs. This approach is ideal for teams that are scaling their agent development and need to balance executive reporting with technical debugging. It provides the flexibility to switch between high-level metrics and detailed analysis without maintaining separate datasets.
Frequently Asked Questions
Can I convert binary datasets to full trajectories later?
No, you cannot recover the detailed execution logs from a binary dataset. Once the intermediate steps are stripped away, that information is lost. If you need diagnostic depth, you must capture it at the time of execution. This is why it is important to choose the right data format from the start of your evaluation process.
How much more storage do full trajectories require?
Full trajectories typically require significantly more storage than binary scores, depending on the complexity of the agent's tasks and the number of tool calls involved. The exact ratio depends on your specific use case, but you should plan for significant storage overhead if you choose this approach.
Are full trajectories necessary for all agent types?
No, full trajectories are not necessary for all agent types. For simple, single-step agents that perform straightforward tasks, binary scores may be sufficient. However, for multi-step agents that use multiple tools and make complex decisions, full trajectories are essential for understanding and improving their behavior.
How do I handle privacy concerns with full trajectories?
Full trajectories can contain sensitive data, such as user inputs or internal system states. You should apply privacy checks and data masking before storing or sharing these datasets. Gold Trace Dataworks includes privacy checks in its data derivation process, ensuring that sensitive information is removed or anonymized while preserving the diagnostic value of the records.
What is the cost difference between the two approaches?
The cost difference is primarily in data processing and storage. Full trajectories require more computational resources to process and more storage to retain. However, the cost of fixing agent failures due to lack of diagnostic information can be much higher than the cost of storing the data. For most teams, the investment in full trajectories is justified by the improvements in agent reliability.
Can I use full trajectories for both training and evaluation?
Yes, but you should be careful to distinguish between the two uses. Full trajectories can be used to select successful examples for training, but you should also retain the failed examples for evaluation and debugging. This ensures that your training data is representative of the full range of agent behaviors, including failures.
Conclusion
The choice between full failure trajectories and binary pass-fail scores depends on your team's goals and the complexity of your agents. For most teams building serious AI agents, full trajectories are the better choice because they provide the diagnostic depth needed to improve reliability and safety. Gold Trace Dataworks can help you build these datasets with traceable sources and documented selection, ensuring that your training data is both high-fidelity and verifiable. To start your project, send a project brief to discuss your specific needs. Learn more: Start a project brief.