
Choose a provider that separates rights metadata from privacy and quality grades if you need to audit legal status independently of data quality. Bundled approaches suit teams that only need a simple pass/fail filter and do not plan to reuse data across different legal contexts. Gold Trace Dataworks builds datasets where a claim about rights remains distinct from an evaluation result, ensuring your training data remains legally defensible and technically accurate.
The Separated Approach
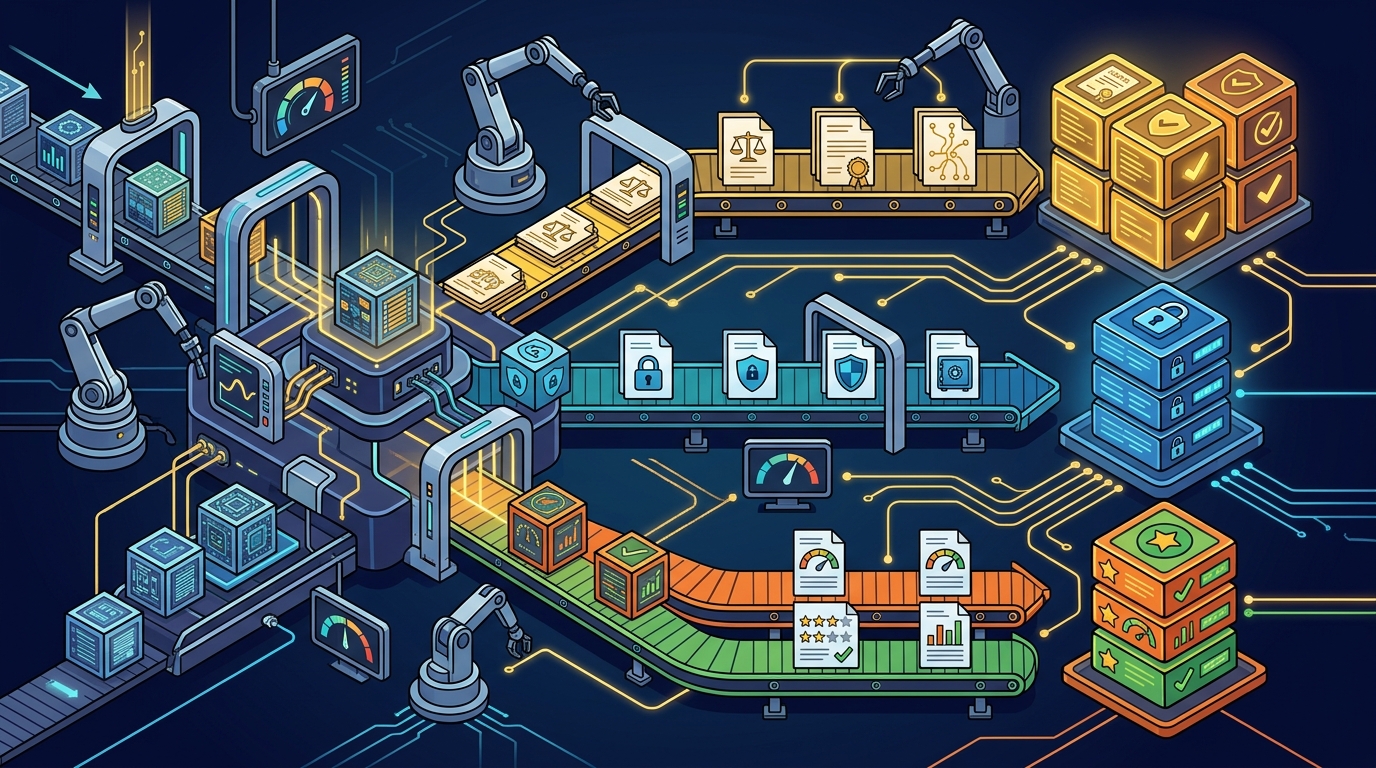
Rights metadata separation is the practice of storing legal permissions, licensing status, and ownership claims in a distinct data layer from technical quality scores and privacy compliance checks. This architecture allows a dataset record to be technically perfect and privacy-compliant while still being legally restricted. In this model, the artifact name does not certify safety or approval. A held or failed record remains an ingot; its permitted use depends on the recorded status, rights, and supporting evidence.
This approach is critical for agent data where the same input might be used for different purposes. A record might pass all quality checks and privacy redactions but still lack the necessary license for commercial deployment. By keeping these signals apart, you can query for data that is high-quality and private, then filter by rights status before training. This prevents the common error of assuming that a clean dataset is automatically a usable dataset.
Gold Trace Dataworks implements this separation in its data contracts. An ingot is a normalized record linked to source hashes and evaluation information. Its disposition is explicit: PASSED, HOLD, QUARANTINED, FAILED, or RIGHTS_ASSERTED. This explicitness ensures that a claim about rights also remains distinct from an evaluation result. You can inspect the evidence that produced a conclusion without treating the projection as the original event.
The Bundled Approach
Bundled metadata is a method where rights, privacy, and quality signals are merged into a single composite score or a single status flag. This approach simplifies the user interface and reduces the number of fields a developer must check. It is often found in general-purpose data cleaning tools that aim for a one-click solution. The logic is straightforward: if the data is not clean, private, and licensed, it is rejected.
The primary limit of this approach is the loss of nuance. If a record fails the composite check, you do not know why. Was it a privacy violation? A quality issue? Or a missing license? This ambiguity makes debugging difficult. It also prevents partial reuse. You cannot take a record that is high-quality but lacks a license and use it for internal research, because the system has already marked it as unusable. This one-size-fits-all filter can lead to the unnecessary discarding of valuable data assets.
For teams that do not need to distinguish between legal and technical failures, this simplicity is a strength. It reduces cognitive load and speeds up the initial ingestion process. However, it creates a black box that is hard to audit. When a legal team asks why a specific record was excluded, the bundled system cannot provide a granular answer. It can only say the record failed the overall check.
Comparison Table
| Criteria | Separated Metadata | Bundled Metadata |
|---|---|---|
| Auditability | High. Each signal is traceable to its source. | Low. Composite scores hide specific failure reasons. |
| Partial Reuse | Supported. Data can be used for non-commercial purposes even if commercial rights are missing. | Not supported. Failed records are typically discarded entirely. |
| Complexity | Higher. Requires managing multiple distinct fields. | Lower. Single status flag simplifies the interface. |
| Legal Defense | Strong. Clear distinction between technical quality and legal status. | Weak. Ambiguity in failure reasons complicates legal review. |
| Best For | Enterprise AI, regulated industries, long-term data assets. | Quick prototypes, simple internal tools, one-off projects. |
Decision Guidance
Choose the separated approach if you are building production-grade AI agents that must operate in regulated environments. If your data will be reused across different projects, or if you need to provide a legal audit trail for every training example, separation is non-negotiable. This is the standard for teams that treat data as a long-term asset rather than a disposable input. Agent Evaluation & Benchmarking services often rely on this separation to ensure that evaluation results are not conflated with licensing issues.
Choose the bundled approach if you are in the early prototyping phase and your primary concern is speed. If you are building a simple internal tool that will not be exposed to external users or legal scrutiny, the simplicity of a single pass/fail flag may be sufficient. This approach minimizes setup time and reduces the number of decisions your team must make during data ingestion. However, be aware that migrating from a bundled system to a separated one later can be costly and complex.
Consider the lifecycle of your data. If you expect to refine your models over years, the investment in separated metadata pays off. You can update rights status without re-evaluating quality, and vice versa. This modularity allows your data infrastructure to evolve alongside your legal and technical requirements. It is a more robust foundation for serious AI development.
Frequently Asked Questions
What is the main risk of bundling rights and quality metadata?
The main risk is the inability to diagnose why a record was rejected. If a record fails the composite check, you cannot determine if it was a legal issue or a technical one. This ambiguity makes it difficult to fix the underlying problem or to reuse the data in a different context where the specific failure might not be relevant.
Can I convert bundled metadata to separated metadata later?
It is possible but often difficult. If the original granular signals were lost when the composite score was created, you cannot recover them. You would need to re-process the raw data to extract the individual signals. This can be time-consuming and may require access to the original source data, which might no longer be available.
How does Gold Trace Dataworks handle rights assertions?
Gold Trace Dataworks uses an explicit disposition system where RIGHTS_ASSERTED is a distinct status from PASSED or FAILED. This ensures that a claim about rights is recorded separately from the evaluation result. The artifact name does not certify safety or approval; its permitted use depends on the recorded status, rights, and supporting evidence.
Is separated metadata more expensive to implement?
It requires more initial setup and management effort. You must define and maintain distinct fields for rights, privacy, and quality. However, this cost is often offset by the ability to reuse data more flexibly and to provide clearer audit trails. For long-term projects, the total cost of ownership is often lower than the cost of re-processing data when legal requirements change.
Does separating metadata affect model training performance?
No, the separation is a metadata layer, not a change to the data content itself. The model trains on the same input and output pairs. The separation affects how you select and filter the data before training. It ensures that you are training on data that is not only high-quality but also legally usable for your specific purpose.
What should I do if I am unsure which approach to choose?
Start by defining your legal and compliance requirements. If you have a legal team that needs to audit data usage, choose separation. If you are building a simple tool with no external exposure, you may start with bundling. However, be prepared to migrate to a separated system as your project grows. Start a project brief to discuss your specific needs with an expert. Learn more: Start a project brief.